Stop Copying from PDFs: Automate Your Data Entry
Table of Contents
- The Hidden Financial Drain of Manual Data Entry
- Why PDFs Are Stubbornly Resistant to Extraction
- The Technical Blueprint of Automation
- A Practical Python Code Example
- The Artificial Intelligence Evolution in Data Extraction
- Real-World Industry Implementations
- Calculating the Return on Investment
- Best Practices for Automation Implementation
- Stop Copying and Pasting: Let Tool1.app Automate Your Data Entry Workflows
- SEO Data Appendices
- Show all
Modern business operations rely heavily on the rapid exchange of information, yet a staggering amount of this data is trapped in static, unstructured formats. Professionals across accounting, logistics, healthcare, and administration waste countless hours every week manually typing numbers, names, and line items from PDF invoices or reports into Excel spreadsheets or Customer Relationship Management systems. This mundane, repetitive task is not just a drain on employee morale; it is a significant financial bottleneck that introduces human error into critical databases. If your team is stuck in a cycle of opening a document, copying a value, switching windows, and pasting it into a cell, it is time to rethink your workflow. You need to automate PDF to Excel data extraction.
The Portable Document Format was designed for visual consistency across different devices and operating systems, essentially acting as digital paper. It was never engineered to be a structured database. Consequently, extracting usable data from it often feels like trying to unbake a cake. However, with the right combination of Python scripting, optical character recognition, and artificial intelligence, businesses can eliminate manual data entry entirely. At Tool1.app, we frequently encounter businesses hemorrhaging resources on these exact manual tasks, and we help them reclaim thousands of hours through intelligent software solutions.
The Hidden Financial Drain of Manual Data Entry
To understand the urgency of automating this process, one must quantify the true cost of manual data entry. It is rarely viewed as a massive expense because it is often hidden within the daily routines of salaried employees. However, when you break down the numbers, the financial impact is startling.
Consider a mid-sized logistics or retail company that processes five hundred invoices and purchase orders per week. If a data entry clerk or an accountant spends just three minutes opening a PDF, locating the relevant data points, copying them into an Excel ledger, and verifying the input, that equates to twenty-five hours of manual labor every single week. Over a year, this amounts to one thousand, three hundred hours. If the average fully burdened cost of that employee is €30 per hour, the company is spending €39,000 annually just to move text from one screen to another.
Furthermore, human error introduces secondary costs. A misplaced decimal point or a transposed digit in financial records or inventory counts can lead to overpayments, stock shortages, or compliance penalties. Correcting these errors often requires hours of forensic auditing. When you automate PDF to Excel pipelines, you are not just saving the €39,000 in labor costs; you are investing in data integrity and operational scalability.
Why PDFs Are Stubbornly Resistant to Extraction
To appreciate the solution, we must understand the technical nature of the problem. A PDF is fundamentally a canvas. When you look at an invoice, your human brain instantly recognizes the layout: the logo is at the top, the total amount is at the bottom right, and the line items are in a structured table in the middle.
A computer reading a standard PDF does not see a table or a structured hierarchy. It sees a collection of text strings with X and Y coordinates on a page. The word “Total” might be at coordinate (400, 800) and the value “€1,250.00” might be at (450, 800). If the invoice generator decides to add a new line item, pushing the total further down the page, the coordinates change entirely.
Additionally, PDFs come in two primary variations. The first is a native or text-based PDF, generated directly from software like Microsoft Word or an ERP system. These files contain a hidden text layer that scripts can interact with directly. The second variation is a scanned PDF, which is essentially a photograph of a document wrapped in a PDF container. These contain no text layer at all, meaning traditional copy-and-paste methods fail completely. Dealing with these variations requires a multi-tiered technical approach.
The Technical Blueprint of Automation
Transitioning from manual data entry to a fully automated pipeline involves creating a software script that mimics the human process of reading, identifying, and transcribing, but does so at lightning speed. Here is the architecture of how a robust automation script reads PDF text and routes it to the correct spreadsheet cell.
Ingestion and Triage
The first step in the automated workflow is file ingestion. Rather than having a human download attachments from emails, a Python script can monitor a dedicated inbox or a specific cloud storage folder. The moment a new file arrives, the script intercepts it. It then determines if the file is a native PDF with accessible text or a scanned image requiring a heavier computational lift.
Text Extraction and Optical Character Recognition
For native PDFs, Python libraries such as PyMuPDF or pdfplumber are incredibly efficient at stripping the embedded text from the document. These tools can analyze the spatial relationships of the text blocks to reconstruct the flow of information.
For scanned documents, the software must deploy Optical Character Recognition. Tools like Tesseract or cloud-based vision application programming interfaces read the pixels of the image and translate them into machine-readable characters. Modern Optical Character Recognition can handle skewed scans, low-resolution artifacts, and even varied typography with high accuracy.
Data Parsing and Pattern Recognition
Once the raw text is extracted, it is just a massive, unformatted string of words and numbers. The script must now act as a detective to find the specific data points required for your Excel sheet.
For highly standardized forms, developers use Regular Expressions. A Regular Expression is a sequence of characters that specifies a search pattern. For example, if you need to extract an invoice number that always follows the format “INV-” followed by six digits, the code can scan the entire document specifically for that exact pattern. Similarly, it can look for date formats or currency symbols.
Structuring and Exporting to Excel
After the target data points—such as Vendor Name, Date, Invoice Number, and Total Amount—are identified and isolated, the script structures them into a virtual table. Using data manipulation libraries like Pandas, the information is formatted into rows and columns. Finally, the script leverages tools like openpyxl to write this structured data directly into an .xlsx file, creating a new row for every processed document, and formatting the cells exactly as your financial team requires.
A Practical Python Code Example
To demonstrate the feasibility of this solution, below is a simplified conceptual example of how Python can be utilized to automate PDF to Excel extraction. While enterprise solutions require far more robust error handling and architecture, this snippet illustrates the core mechanism of extracting text and writing it to a spreadsheet.
Python
import pdfplumber
import pandas as pd
import re

# Define the path to the incoming invoice and the output Excel file
pdf_path = "incoming_invoice_001.pdf"
excel_path = "financial_records.xlsx"

# Initialize variables to hold our extracted data
invoice_data = {
    "Invoice_Number": None,
    "Date": None,
    "Total_Amount": None
}

# Open the PDF and extract text from the first page
with pdfplumber.open(pdf_path) as pdf:
    first_page = pdf.pages[0]
    text_content = first_page.extract_text()

# Use Regular Expressions to find specific patterns in the text
# Assuming invoice numbers look like INV-12345
invoice_match = re.search(r"INV-d{5}", text_content)
if invoice_match:
    invoice_data["Invoice_Number"] = invoice_match.group(0)

# Assuming dates are in DD/MM/YYYY format
date_match = re.search(r"d{2}/d{2}/d{4}", text_content)
if date_match:
    invoice_data["Date"] = date_match.group(0)

# Assuming the total amount is preceded by "Total: €"
amount_match = re.search(r"Total:s*€([0-9.,]+)", text_content)
if amount_match:
    invoice_data["Total_Amount"] = amount_match.group(1)

# Convert the extracted dictionary into a Pandas DataFrame
df = pd.DataFrame([invoice_data])

# Append the new data to an existing Excel file
try:
    # Read existing data to append without overwriting
    existing_df = pd.read_excel(excel_path)
    updated_df = pd.concat([existing_df, df], ignore_index=True)
    updated_df.to_excel(excel_path, index=False)
    print("Data successfully extracted and appended to Excel.")
except FileNotFoundError:
    # If the Excel file doesn't exist yet, create it
    df.to_excel(excel_path, index=False)
    print("New Excel file created with extracted data.")
In this script, the software effortlessly ignores all the irrelevant boilerplate text on the invoice and zeros in precisely on the three data points needed for the accounting ledger. This task, which takes a human several seconds of cognitive load per document, is executed by the machine in milliseconds.
The Artificial Intelligence Evolution in Data Extraction
The script provided above works beautifully if all your vendors send invoices with predictable, standardized layouts. But business is rarely that neat. What happens when Vendor A calls their identifier an “Invoice Number”, Vendor B calls it a “Reference ID”, and Vendor C calls it a “Transaction Code”? What if the layout changes completely from month to month?
Writing custom Regular Expressions for every single vendor does not scale. This is where custom software architecture from Tool1.app comes into play, integrating Large Language Models and advanced Machine Learning into the data extraction pipeline.
Instead of telling the software exactly where to look or what exact pattern to find, we can train the software to understand the context of the document. By passing the extracted raw text through a secure, finely-tuned AI model, the system can interpret the unstructured data just like a human would. You simply prompt the system: “Extract the vendor name, the date of the transaction, and the final total amount due.”
The AI understands that “Reference ID: 8990” and “Invoice Number: 8990” serve the exact same semantic purpose. It understands that a total might be listed under a column named “Amount Due” even if the word “Total” is never explicitly used. This cognitive flexibility means your automation pipeline rarely breaks when a partner updates their invoice design. It routes the intelligent output directly to the designated Excel cells, achieving near-perfect accuracy across highly diverse document pools.
Real-World Industry Implementations
To contextualize the impact of this technology, let us examine how different industries apply these automated data pipelines to solve severe operational bottlenecks.
Accounting and Bookkeeping Firms
Accounting firms are inundated with a massive variety of financial documents, especially during tax season. Clients upload a chaotic mix of digital receipts, bank statements, and vendor invoices. Traditionally, junior accountants would spend their days manually transcribing this data into Excel sheets or directly into software like Xero or QuickBooks.
By implementing an automated extraction system, these firms can have client uploads automatically scanned upon receipt. The automation script identifies the vendor, the date, the tax amount, and the net total, categorizes the expense based on historical data, and drops it into a formatted Excel reconciliation sheet. The junior accountants transition from data typists to data reviewers, stepping in only when the system flags a document with a low confidence score. This drastically increases the volume of clients a firm can handle without expanding their payroll.
Logistics and Supply Chain Management
In the logistics sector, speed and accuracy are paramount. Bill of Lading documents, packing slips, and customs declarations frequently arrive in PDF format via email. Dispatchers need to extract the weight, dimensions, destination addresses, and pallet counts to organize shipments and calculate freight costs.
A manual copy-paste error here is catastrophic; sending a truck to the wrong postal code or underestimating a load weight can cost thousands of Euros in delays and fines. An automated pipeline intercepts these shipping documents, extracts the critical logistics data using intelligent spatial mapping, and populates a master operational Excel tracking sheet. This allows warehouse managers to see real-time incoming freight data instantly, optimizing dock scheduling and route planning.
Healthcare Administration
Healthcare providers manage an overwhelming amount of unstructured patient data. Referral letters, lab results, and patient intake forms are often scanned and saved as PDFs. Medical administrators must manually comb through these documents to update patient records or insurance billing spreadsheets.
An automated solution can securely process these PDFs, extracting patient identification numbers, diagnosis codes, and treatment dates, routing them securely to the relevant administrative spreadsheets. Given the stringent compliance requirements surrounding healthcare data, these automated systems can be deployed on localized, highly secure servers, ensuring that no patient data ever leaves the clinic’s internal network while still eliminating the manual transcription burden.
Calculating the Return on Investment
When business leaders consider investing in custom automation, the primary question is always regarding the return on investment. The mathematics heavily favor automation, often showing a positive return within the first few months of deployment.
Let us return to our previous example of the company spending €39,000 annually on manual data entry. To build and deploy a custom, highly reliable, AI-driven PDF extraction tool tailored specifically to their document types and integrated with their specific Excel and database infrastructure, the upfront development cost might range from €5,000 to €15,000, depending on complexity.
Even at the higher end of that estimate, the software pays for itself in less than six months. From that point forward, the €39,000 annual expense is virtually eliminated, transforming into pure operational profit. Furthermore, the software does not take vacations, it does not get fatigued at the end of a Friday shift, and it can scale instantly. If the company’s invoice volume doubles from five hundred to one thousand per week, the automated system handles the increase seamlessly without requiring the HR department to hire and train another €30,000-per-year clerk.
Best Practices for Automation Implementation
Building a successful automated workflow requires more than just writing a script; it requires a strategic approach to software integration.
Establish a Human-in-the-Loop Protocol
No automated system is completely infallible, especially when dealing with poor-quality scanned documents or handwriting. The most effective systems utilize a “human-in-the-loop” design. The software processes the PDFs and assigns a confidence score to its extraction. If the AI is highly confident (e.g., above 98%), the data is routed directly to Excel. If a document is blurry or confusing and the confidence score drops below a predetermined threshold, the software flags that specific document and routes it to a human operator for a quick manual review. This ensures 100% data integrity while still automating the vast majority of the workload.
Maintain Strict Data Security
When handling invoices, employee records, or client data, security cannot be an afterthought. Automated scripts should process files in secure, encrypted environments. If leveraging cloud-based AI models, it is vital to utilize enterprise-tier APIs that guarantee data is not retained or used to train public models. Temporary files generated during the text extraction process should be programmatically deleted immediately after the data is successfully written to the Excel file.
Design for Scalability
As your business grows, your automation tools should grow with you. Hardcoding absolute file paths or relying on a single employee’s desktop computer to run the script is a recipe for failure. Modern automations should be deployed in cloud environments or as serverless functions, capable of parallel processing. Whether you receive ten PDFs a day or ten thousand, the architecture should process them with the same speed and reliability.
Stop Copying and Pasting: Let Tool1.app Automate Your Data Entry Workflows
The era of paying skilled professionals to act as human bridges between digital documents and spreadsheets is over. The technology to read, interpret, and organize unstructured data is accessible, affordable, and incredibly powerful. Every hour your team spends manually copying from a PDF and pasting into a cell is an hour stolen from strategic planning, customer service, and business growth. It is time to modernize your operations and turn your static documents into dynamic, instantly accessible data.
If you are ready to eliminate manual data entry, streamline your operations, and drastically reduce human error, you need a custom solution tailored to your exact workflows. Stop copying and pasting. Let Tool1.app automate your data entry workflows. Our engineering team specializes in building intelligent, secure, and highly scalable automation pipelines that transform how your business handles data. Contact us today for a consultation, and discover how quickly we can turn your operational bottlenecks into competitive advantages.
SEO Data Appendices
- SEO Title: Stop Copying from PDFs: Automate PDF to Excel Data Entry
- Meta Description: Discover how to automate PDF to Excel data entry using Python and AI. Stop wasting hours on manual extraction and let custom software streamline your workflow.
- Focus Keyword: automate PDF to Excel
- Blog Post Tags: python, automation, ai, software development, data extraction, business efficiency
- Page Slug: automate-pdf-to-excel-data-entry
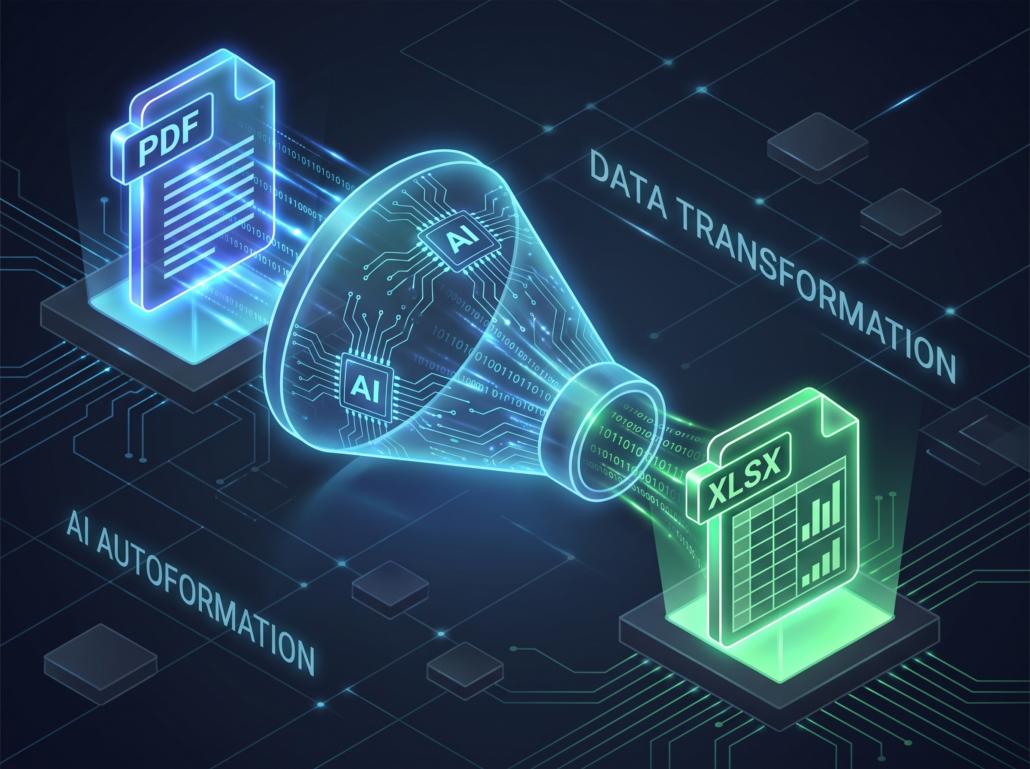
- English image generation prompt: A highly detailed, modern isometric illustration of a glowing PDF document transforming into a structured Excel spreadsheet through a glowing digital funnel, representing automation and artificial intelligence, sleek tech aesthetic, dark mode with neon blue and green accents, highly professional, 8k resolution.


Leave a Reply
Want to join the discussion?Feel free to contribute!
Join the Discussion
To prevent spam and maintain a high-quality community, please log in or register to post a comment.